Study Guide
A Next.js PWA that transforms uploaded lecture files (PDF, DOCX, PPTX, Markdown) into structured topic-based study notes with AI summaries, a guided reader, and browser text-to-speech. Built solo with Supabase, Drizzle, Inngest, and Gemini.
- Role
- Solo full-stack developer & product designer
- Timeline
- 3 months
- Status
- Experimental
Result End-to-end study loop: upload files → background pipeline extracts text, detects chapters/topics, generates per-topic summaries → one-topic-at-a-time reader with three summary modes, auto-advance TTS, and resumable progress.
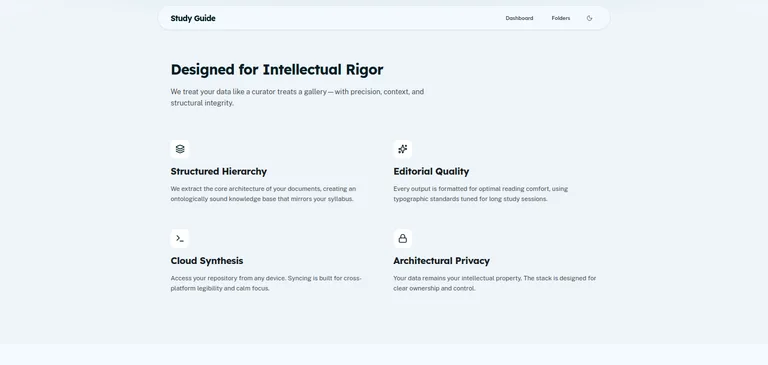
1 / 8
Overview
Students upload course files (PDF, DOCX, PPTX, TXT, MD) into private folders. The backend pipeline downloads from Supabase Storage, extracts normalized text, calls Gemini to detect chapters and topics, and generates structured summaries (short/medium/detailed) with key terms, important points, and examples. The guided reader shows one topic at a time, lets users toggle summary length, supports browser SpeechSynthesis with chunked playback and auto-next within chapters, and saves session state (document, chapter, topic, mode, speech rate) for seamless resume. Built on Next.js 16 App Router with a full Drizzle ORM schema, Supabase auth/storage, and Inngest for durable background jobs.
The problem
Students accumulate dozens of lecture files but have no efficient way to review them. Manual rereading is slow, extracting key points is tedious, maintaining study momentum across sessions is hard, and heterogeneous file formats (PDF, DOCX, PPTX, etc.) make automated processing brittle.
The solution
A multi-stage background document pipeline (download → extract → normalize → outline → summarize → mark ready/failed) with a polished guided reader. The reader handles chunked TTS, chapter-boundary auto-advance stops, manual next/previous/chapter navigation, summary mode switching mid-session, and full progress persistence to the database.
Process
1. Defined MVP scope, tech stack, and product plan. 2. Set up Next.js 16 + Supabase + Drizzle ORM. 3. Designed relational schema (folders, documents, extracts, chapters, topics, summaries, sessions, progress). 4. Built upload flow with signed URLs and direct-to-Storage uploads. 5. Implemented file parsers for PDF, DOCX, PPTX, TXT, MD. 6. Integrated Gemini API for chapter/topic detection and structured JSON summary generation. 7. Built the reader component with SpeechSynthesis, summary mode switching, auto-next, and progress tracking. 8. Added reprocessing, error handling, and failure recovery. 9. Styled everything with Tailwind CSS 4 + shadcn/ui + Base UI.
What I learned
Multi-step document pipelines need durable retry logic at every stage. Gemini prompt engineering is critical for consistent chapter/topic boundary detection. Browser SpeechSynthesis works for MVP but requires utterance chunking for reliable long-form playback. A normalized schema makes partial reprocessing and recovery straightforward. Designing for self-hostability from day one (clear env setup, SQL schema files, documented stack) adds initial overhead but pays off for a portfolio project.
Features
- Folder CRUD
- multi-format upload via signed URLs
- background processing pipeline with status tracking
- AI chapter/topic detection
- per-topic summaries (short/medium/detailed)
- guided reader with summary mode toggle
- browser TTS with chunked playback
- auto-next within chapters with chapter-complete affordance
- manual next/previous/chapter navigation
- study session persistence and resume
- per-topic progress tracking
- document reprocessing
- PWA manifest
- Supabase auth (email + Google OAuth)
- row-level security
- dark/light theme
Results
- A fully functional, deployable study app with end-to-end flow.
- Pipeline reliably processes PDF, DOCX, PPTX, TXT, and MD through extraction, chapter detection, and multi-level summary generation.
- Reader handles topic navigation, summary switching, speech playback, auto-advance, and progress persistence.
- Entire stack is self-hostable with documented setup.
My contribution
- Full-stack architecture & development
- database schema design
- auth & storage integration
- document processing pipeline
- UI/UX design
- reader & TTS implementation
- progress tracking
- PWA configuration
- product planning & documentation